How to measure AI visibility: a practical tracker, audit, and reporting system
Measure AI visibility with a fixed prompt set, raw answer records, citation and mention metrics, and a reporting loop that sends each signal to a page decision.
Growth engineers, SEO leads, and agencies building a trustworthy AI visibility measurement system
AI visibility / AI visibility tracker
A single AI visibility score can look reassuring while hiding the only facts your team needs: which prompt changed, which answer surface changed, what source was cited, and which page deserves work. If the raw observation is missing, the chart is not a decision tool.
A workable system has four parts: a stable prompt frame, repeatable runs, an evidence record for every answer, and a review loop that assigns one next action. This guide shows the method, the limits, and a copyable API request for building the prompt set.
Best Next Step
Turn AI visibility into a real measurement system
Use AgentSEO to build a stable prompt set, map it to owned pages, and hand the resulting evidence requirements to the workflow that collects and reviews it.
Start with the three jobs: tracker, audit, and dashboard
Most teams combine three different jobs into one vague metric and then wonder why the dashboard feels fake.
An AI visibility tracker answers a narrow question: did we appear for this prompt family on this platform this week. An audit answers a diagnostic question: why are we missing, who is winning, and what sources are being trusted instead. A dashboard answers a management question: where is movement happening and what should the team do next.
Those jobs support each other, but they are not the same thing. If you compress them into one score, you lose the operator value of each layer. The tracker becomes too vague, the audit becomes too shallow, and the dashboard becomes decorative.
| Layer | Question it answers | Output |
|---|---|---|
| Tracker | Did we appear, get cited, or move this week? | Prompt-level observations across platforms. |
| Audit | Why did we lose or gain visibility here? | Source analysis, competitor review, page hypotheses. |
| Dashboard | What needs action first? | A prioritized work queue for pages, prompts, and owners. |
The live SERP splits the method question from the tool question
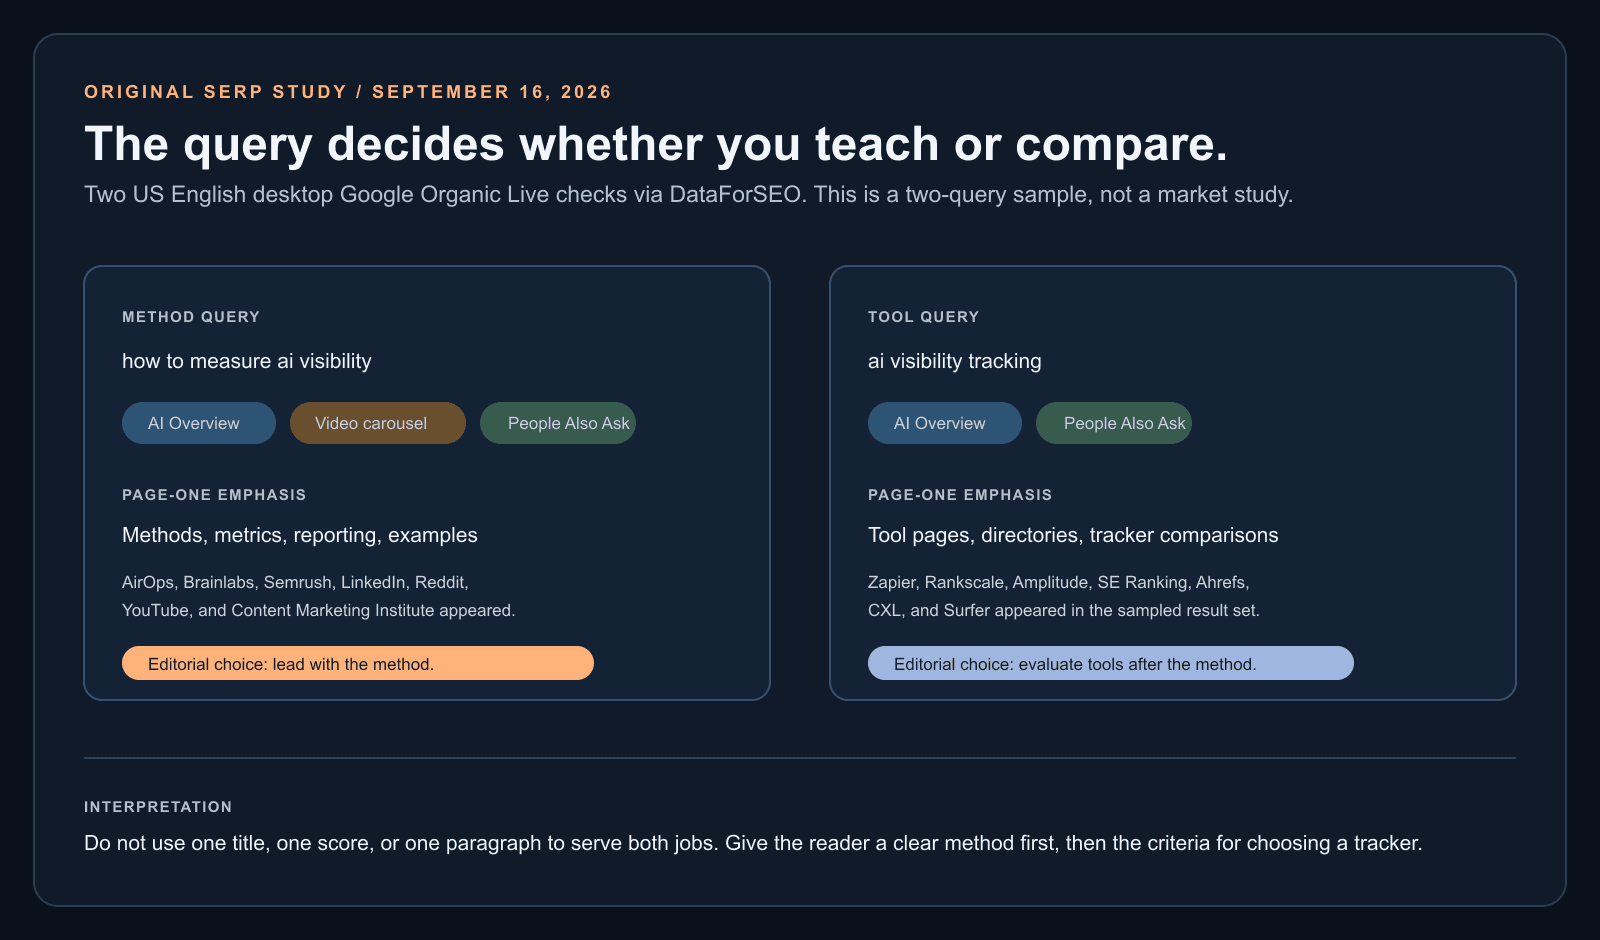
A small US desktop study shows why this page should teach a measurement method before it talks about software.
On September 16, 2026, we ran two US English desktop Google Organic Live checks through DataForSEO. The query how to measure AI visibility returned an AI Overview, video carousel, and People Also Ask. Its first eight organic results were mainly method and reporting pages from AirOps, Brainlabs, Semrush, a LinkedIn article, a Reddit discussion, YouTube, and Content Marketing Institute.
The adjacent query AI visibility tracking returned an AI Overview and People Also Ask too, but its organic results leaned toward tool directories, product pages, and tracker comparisons. That is a different reader job. The first query asks for a defensible method. The second often asks what software to evaluate. Mixing those jobs makes a page less useful to both readers.
This is a two-query snapshot, not a market-size study or ranking-factor claim. It is enough to guide this update: lead with the method, make the operating record concrete, and let the tool section support the workflow rather than swallow it.
| Query | Observed result features | What page one emphasized | Editorial decision |
|---|---|---|---|
| how to measure ai visibility | AI Overview, video carousel, People Also Ask | Method, metrics, reporting, and practical examples | Answer the measurement workflow first. |
| ai visibility tracking | AI Overview and People Also Ask | Tracker tools, product pages, and comparison lists | Explain tool requirements after the method. |
Write the measurement contract before you run a tracker
The score comes last. First agree on what one observation means and what it does not mean.
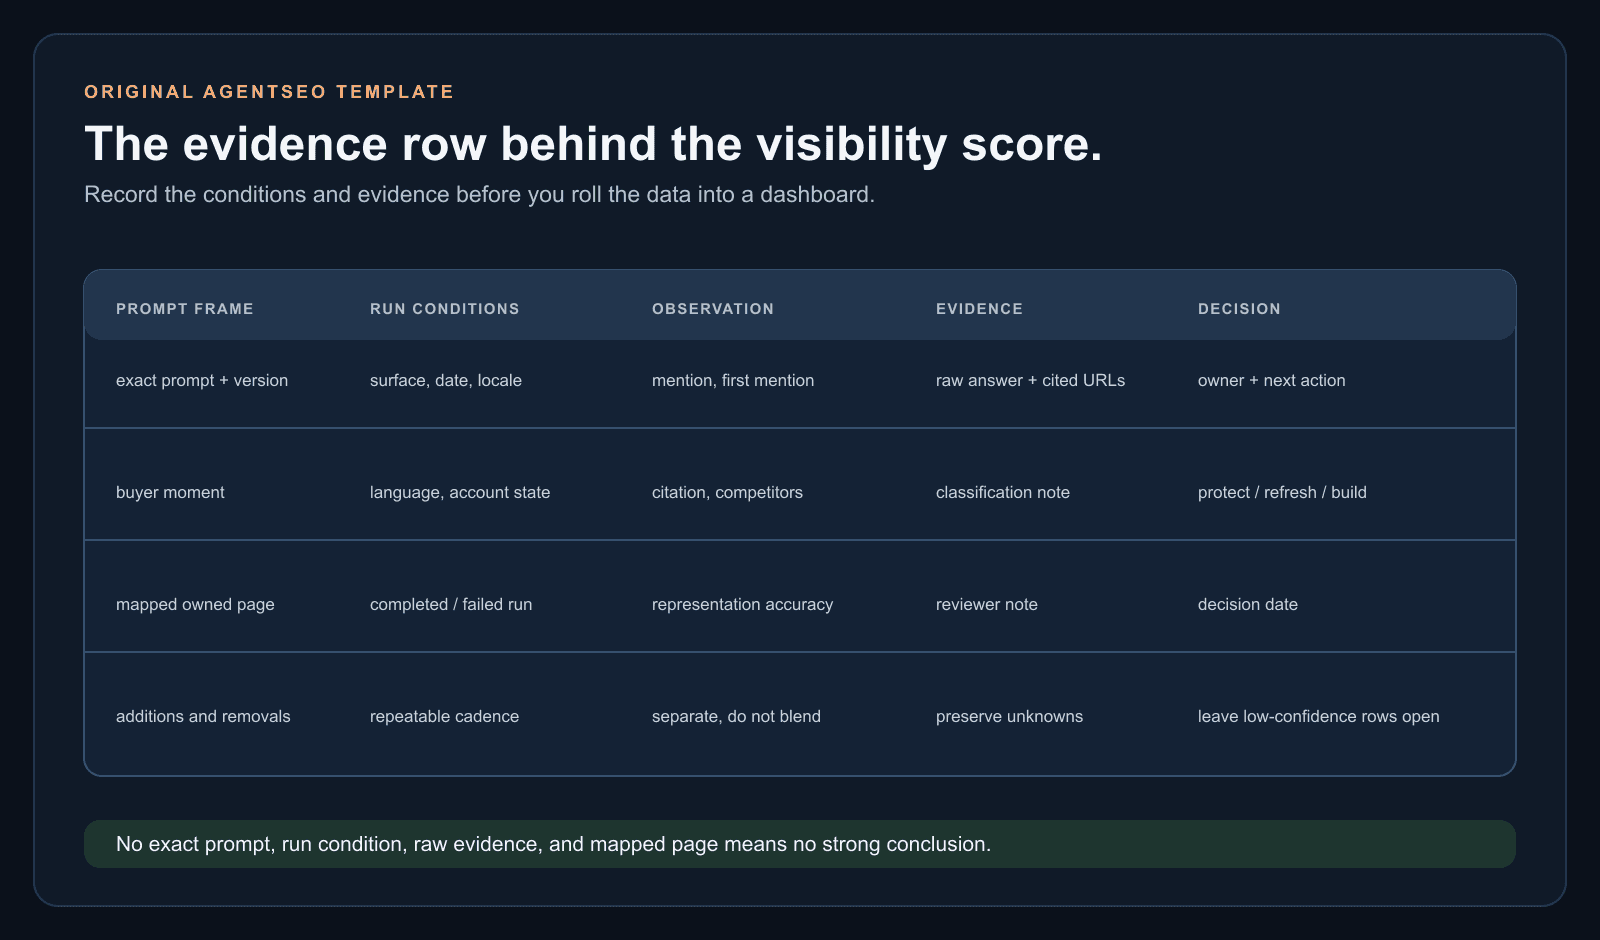
A measurement contract is a short written rule for the team. It names the prompt frame, surfaces, locale, run cadence, classification rules, and decision threshold. Without it, a dashboard can change because somebody added prompts, switched countries, altered a competitor list, or silently treated a timeout as a non-mention.
You do not need a statistical model to begin. You do need enough context that another operator can inspect one row and reach the same conclusion. Start with a small diagnostic set. Expand only after you know which buyer questions and surfaces matter.
{
  "prompt_id": "comparison-seo-api-v1-03",
  "prompt": "[exact saved prompt]",
  "surface": "[platform or Google feature]",
  "run_at": "[ISO timestamp]",
  "locale": "United States",
  "language": "en",
  "raw_answer": "[stored response or approved reference]",
  "target_mentioned": "[true, false, or unknown]",
  "first_mention_position": "[integer or null]",
  "citations": "[captured citations]",
  "cited_urls": "[captured URLs]",
  "competitors_mentioned": "[captured competitors]",
  "mapped_asset_url": "[owned page or null]",
  "run_status": "[completed, failed, or incomplete]",
  "review_note": "[what changed and what to do next]"
}| Field | Rule | Why it protects the result |
|---|---|---|
| Prompt frame and version | Keep the active set stable; log additions and removals. | Prevents a changing question set from looking like performance movement. |
| Run conditions | Save surface, date, locale, language, and account state when known. | Makes a result comparable and debuggable. |
| Classification | Define mention, first mention, recommendation, citation, and failed run separately. | Stops one broad label from hiding contradictory evidence. |
| Evidence row | Preserve the raw answer, URLs, competitor names, and review note. | Lets an operator audit a chart and route a page fix. |
| Decision rule | Name the owner and next action for a meaningful change. | Turns monitoring into work, not reporting theater. |
Use Search Console as one layer, not the whole measurement stack
Google now gives you more visibility into generative AI performance, but it still does not replace prompt tracking or page diagnosis.
Google announced dedicated Search Console performance reports for generative AI features on June 3, 2026, and said the rollout reached all websites worldwide on August 31. The reports provide Google-side impressions, pages, countries, devices for Search, and time trends for supported generative AI features. That is a real step forward, and serious teams should use it.
It is still only one layer. Search Console can tell you that supported Google generative-AI visibility changed. It does not preserve a cross-platform prompt set, competitor frame, raw answer, citation path, or the next fix the team should make.
Google's own guidance is also useful here: you do not need special AI files or special schema to appear in Google AI features. The better move is still strong SEO fundamentals, helpful pages, and measurement that ties visibility back to owned assets.
Related reading
| Layer | Best for | What it still cannot answer alone |
|---|---|---|
| Search Console generative AI reports | Google-side discoverability trends and impression movement | Exact prompt behavior, competitor context, and page-level remediation |
| Prompt tracker | Repeated answer behavior across platforms and prompt families | Whether the page is also gaining classic search visibility |
| Page audit | Explaining why one URL earned or lost trust | Whether the change is widespread across the monitored prompt set |
The metrics that survive scrutiny
You need a compact set of metrics that help a working team make better page decisions.
The most useful KPIs are prompt-specific and frequency-based. Start with mention rate: how often your brand appears across repeated runs of the same prompt set. Then track first mention rate, because being named first on a high-intent prompt is more valuable than being buried in a list.
Next, track citations and source mix. If a model keeps citing your docs, your blog, a review site, Reddit, or a competitor comparison page, that tells you where trust is accumulating. That is actionable. A blended score without prompt context is not.
- Mention rate by prompt set and platform.
- First mention rate for buying or comparison prompts.
- Citation rate and cited URL distribution.
- Representation accuracy for the claims that matter to the buyer.
- Competitor share on the same monitored prompts.
- Referral, branded-search, and conversion movement as separate outcome signals.
Review this week's AI visibility data.

For each prompt family, return:
- mention rate
- first mention rate
- citation rate
- representation accuracy for the agreed product or category claims
- top cited URL
- top competitor overlap
- whether Search Console generative AI performance moved too
- the page or asset that should be reviewed next

Then classify each row:
- protect
- refresh
- build
- monitor only| Prompt family | Example prompt | Why it matters |
|---|---|---|
| Category | best seo api for ai agents | Checks broad market framing and list inclusion. |
| Measurement | how to measure ai visibility | Checks whether your educational assets earn entry points. |
| Comparison | AgentSEO vs generic SERP API | Checks buying-intent trust and owned-asset citations. |
| Workflow | how to build an seo agent | Checks operator intent and implementation relevance. |
| Brand + use case | AgentSEO Claude Code workflow | Checks whether branded operational queries map back to your site. |
Build a prompt set you can defend
A prompt library should represent buyer decisions, not every phrase a model can autocomplete.
Start with the questions that change a buyer's shortlist: category discovery, comparison, implementation, problem diagnosis, and brand-plus-use-case. Map each prompt to an owned page. An unmapped prompt is not a reporting failure. It is a content or positioning hypothesis waiting for review.
Do not claim that a twelve-prompt diagnostic is a complete market estimate. It is a starting frame for finding obvious gaps. The frame becomes more useful when you save its version, repeat the same conditions, and add prompts deliberately rather than inflating the denominator whenever a new idea appears.
AgentSEO's prompt-set endpoint is built for that planning step. It generates a structured prompt set and the associated measurement schema. It does not run live LLM or AI-search queries in version one; keep the collection layer and the planning layer distinct.
curl -X POST https://www.agentseo.dev/api/v1/ai-visibility/prompt-set?sync=true \
  -H "x-api-key: sk_live_..." \
  -H "Content-Type: application/json" \
  -d '{
    "target": "Your brand",
    "category": "Your category",
    "audience": "Your primary buyer",
    "locale": "United States",
    "platforms": ["chatgpt", "perplexity", "google_ai"],
    "competitors": ["Competitor A", "Competitor B"],
    "topics": ["category discovery", "implementation", "comparison"],
    "owned_assets": [{
      "url": "https://example.com/your-page",
      "title": "Your supporting page",
      "page_type": "blog_post",
      "topics": ["category discovery"]
    }],
    "prompt_count": 12,
    "cadence": "weekly",
    "include_citation_checks": true,
    "include_competitor_checks": true
}'| Buyer moment | What you capture | What the review can change |
|---|---|---|
| Category discovery | Whether you are included and how you are described | Category page positioning, proof, or a missing explainer |
| Comparison | First mention, competitors, citations, and recommendation framing | Comparison page evidence, pricing clarity, or third-party proof |
| Implementation | Cited docs, missing steps, and source mix | Documentation, examples, or integration guides |
| Problem diagnosis | The language and sources used to answer a pain point | Problem-aware content or a support asset |
Build a weekly loop the team can actually run
A small repeatable loop beats a massive dashboard nobody trusts.
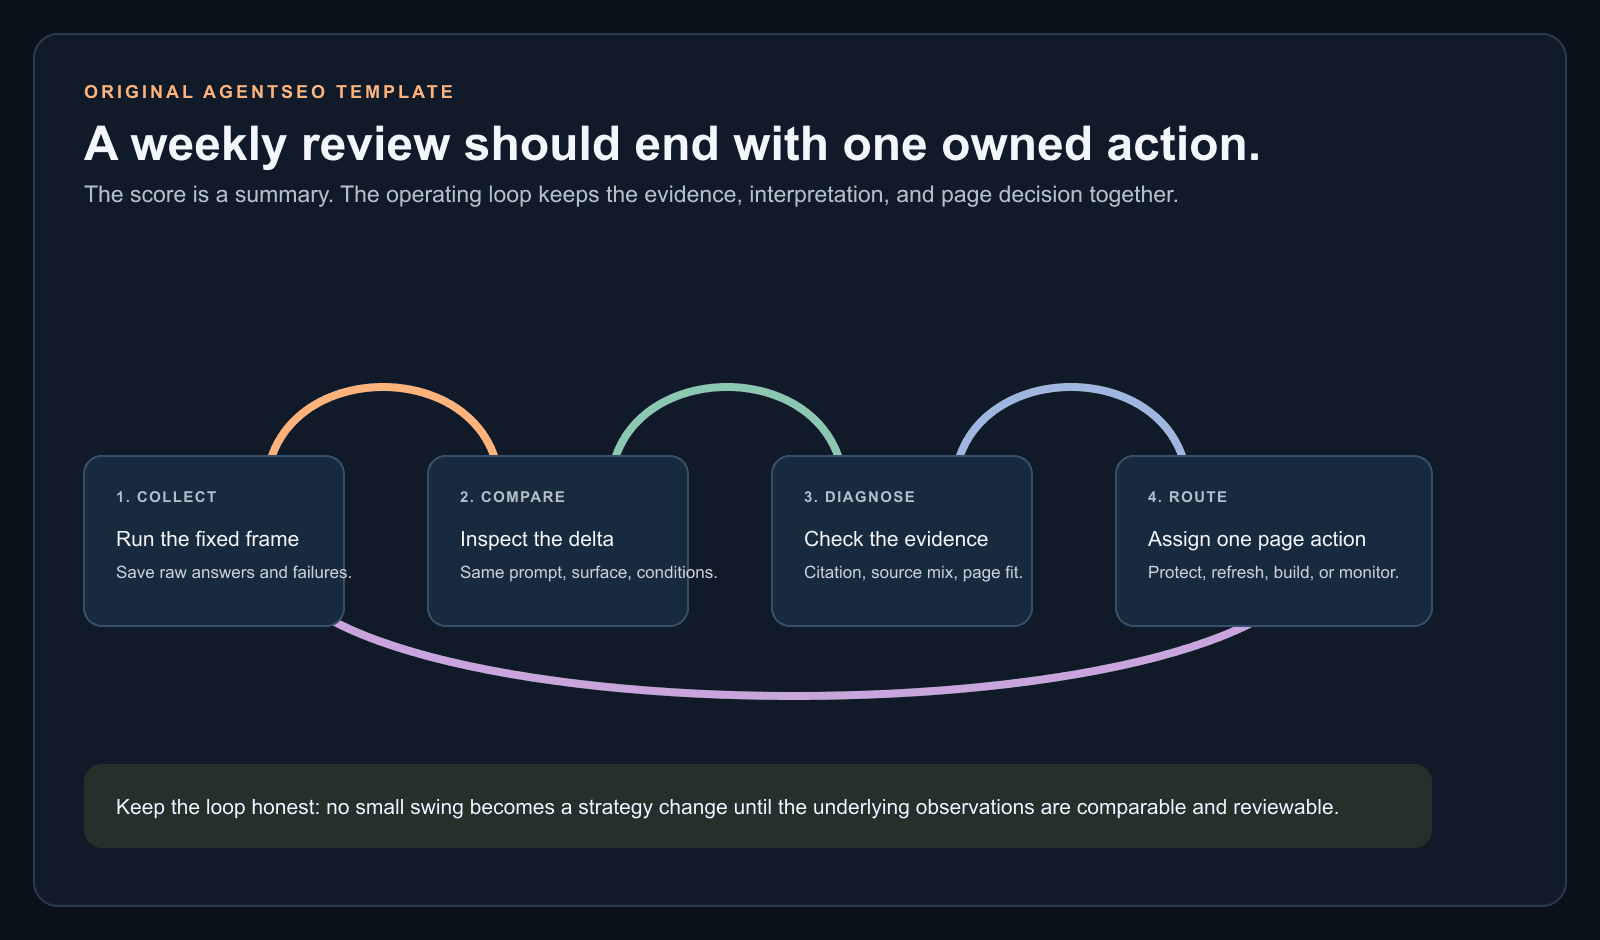
Start with a manageable prompt frame across category, comparison, workflow, and problem-aware intent. Run it on the surfaces that matter to your buyer. Save the raw answer, mention result, cited URLs, competitor frame, and failed runs. Then review deltas, not isolated screenshots.
Interpret the first runs as diagnostics, not a verdict. Weak mention rate beside strong rankings can justify checking representation or source-trust gaps. Strong mentions beside weak rankings can justify checking whether the brand is understood but the owned assets are thin. Both are hypotheses until the underlying evidence holds up across repeated comparable runs.
Related reading
{
  "prompt_id": "[saved prompt ID]",
  "platform": "[surface]",
  "brand_mentioned": "[true, false, or unknown]",
  "first_mentioned": "[true, false, or unknown]",
  "cited_urls": ["[captured URL]"],
  "competitors_present": ["[captured competitor]"],
  "run_date": "[ISO date]",
  "next_action": "[specific page decision]"
}| Step | What you save | Why it matters |
|---|---|---|
| Run prompts | Prompt, platform, date | Preserves the exact measurement context. |
| Store outcomes | Mention state, first mention, citations, competitors | Lets you compare behavior instead of opinions. |
| Review changes | Wins, losses, and new source patterns | Creates hypotheses worth testing. |
| Assign work | Page owner and next edit | Turns monitoring into action instead of reporting theater. |
What good AI visibility tools actually do
The useful tool shape is less magical than most vendor pages suggest.
Evaluate a tool by what it preserves, not by how confident its headline score looks. At minimum, it should expose the prompt set, surface, run conditions, cited sources, competitor frame, and the raw evidence behind a change. Then you can compare like with like and route the result to a page.
The current tracker SERP is crowded with product pages and comparison lists. That makes the data contract more important, not less. Ask every vendor how a mention is classified, how failed runs are shown, whether source URLs are retained, and what changes when the prompt set is edited.
- Fixed prompt sets and scheduled reruns.
- Saved citations and cited URL history.
- Competitor overlap on the same prompt families.
- Page-level routing so edits can be assigned and reviewed.
- Enough structure to connect AI visibility with classic search and pipeline signals.
| Capability | Why it matters | Weak version | Strong version |
|---|---|---|---|
| Prompt preservation | You cannot compare movement if the prompt set keeps drifting | Ad hoc prompts and screenshots | Saved prompt families and rerunnable checks |
| Citation history | Source trust matters as much as brand mention | Counts mentions only | Stores cited URLs and source mix over time |
| Page routing | Teams need a page to fix, not just a chart to admire | No owned-page mapping | Each change points to a page, owner, or queue |
| Cross-platform evidence | One platform can mislead you | Single-surface view | Platform-specific rows with preserved answer context |
Where AgentSEO fits in the measurement stack
The real win is turning AI visibility from ad hoc checking into a workflow with evidence.
AgentSEO fits the planning and workflow layer. Its AI visibility prompt-set endpoint maps stable prompt families to platforms, competitors, owned assets, measurement fields, and follow-on audit jobs. That is useful for growth engineers, technical marketers, and agencies that need a reproducible starting frame instead of another ad hoc spreadsheet.
It is not a claim that AgentSEO observes every live answer surface in the endpoint described here. Keep collection, evidence storage, and interpretation explicit. The leverage is a cleaner operating loop with enough structure to earn trust.
Keep the workflow moving
Turn AI visibility into a real measurement system
Use AgentSEO to build a stable prompt set, map it to owned pages, and hand the resulting evidence requirements to the workflow that collects and reviews it.
Daniel Martin
Cofounder, AgentSEO
Inc. 5000 Honoree and cofounder of AgentSEO and Joy Technologies. Daniel has helped 600+ B2B companies grow through search and now writes about practical SEO infrastructure for AI agents, MCP workflows, and REST-first execution systems.
FAQ
Questions teams usually ask next
Can I measure AI visibility with one score?
You can create one, but it will hide the useful detail. Mention rate, first mention, citation source mix, platform differences, and page-level movement are more actionable than a blended index.
How often should I run AI visibility checks?
Choose a cadence that matches the decision. Weekly can work for an active program, but do not overread one run. Preserve run conditions, compare repeated observations, and make the reporting cadence slower than the collection cadence when the signal is noisy.
What matters more, mentions or citations?
Both matter, but they answer different questions. Mentions tell you whether you entered the answer. Citations tell you which assets and surfaces the model trusted enough to reference.
What should an AI visibility audit include?
It should include a versioned prompt set, platform-specific observations, saved raw answers and citations, failed-run handling, competitor overlap, and page-level hypotheses about what to improve next.
Can Google Search Console measure AI visibility?
It can measure supported Google generative-AI impressions and related page, country, device, and time dimensions. It cannot replace a cross-platform prompt tracker because it does not expose the raw AI answer, a competitor frame, or visibility on other answer engines.
More in this topic
AI visibility and AI search
Measurement
AI search reporting dashboard: what to track, what to show, and what to ignore
Build an AI search reporting dashboard that shows visibility, cited pages, competitors, business context, owners, and the next action. Includes a copyable prompt and template.
AI visibility
Google AI Mode guide: what it is, what changed, and how to adapt SEO
Learn what Google AI Mode is, how it works, how it differs from AI Overviews, and what Google's official guidance means for SEO in 2026.